AI video generation basics: making video from text and images
AI video is a technology that draws many pictures in a row so they fit together over time. This guide explains how it works, three ways to start, and how to write prompts that include the camera.
한국어English
Based on: official documentation and research blogs from OpenAI, Google, and Stability AI (posts from 2021, 2023, and 2024). Checked in September 2026.
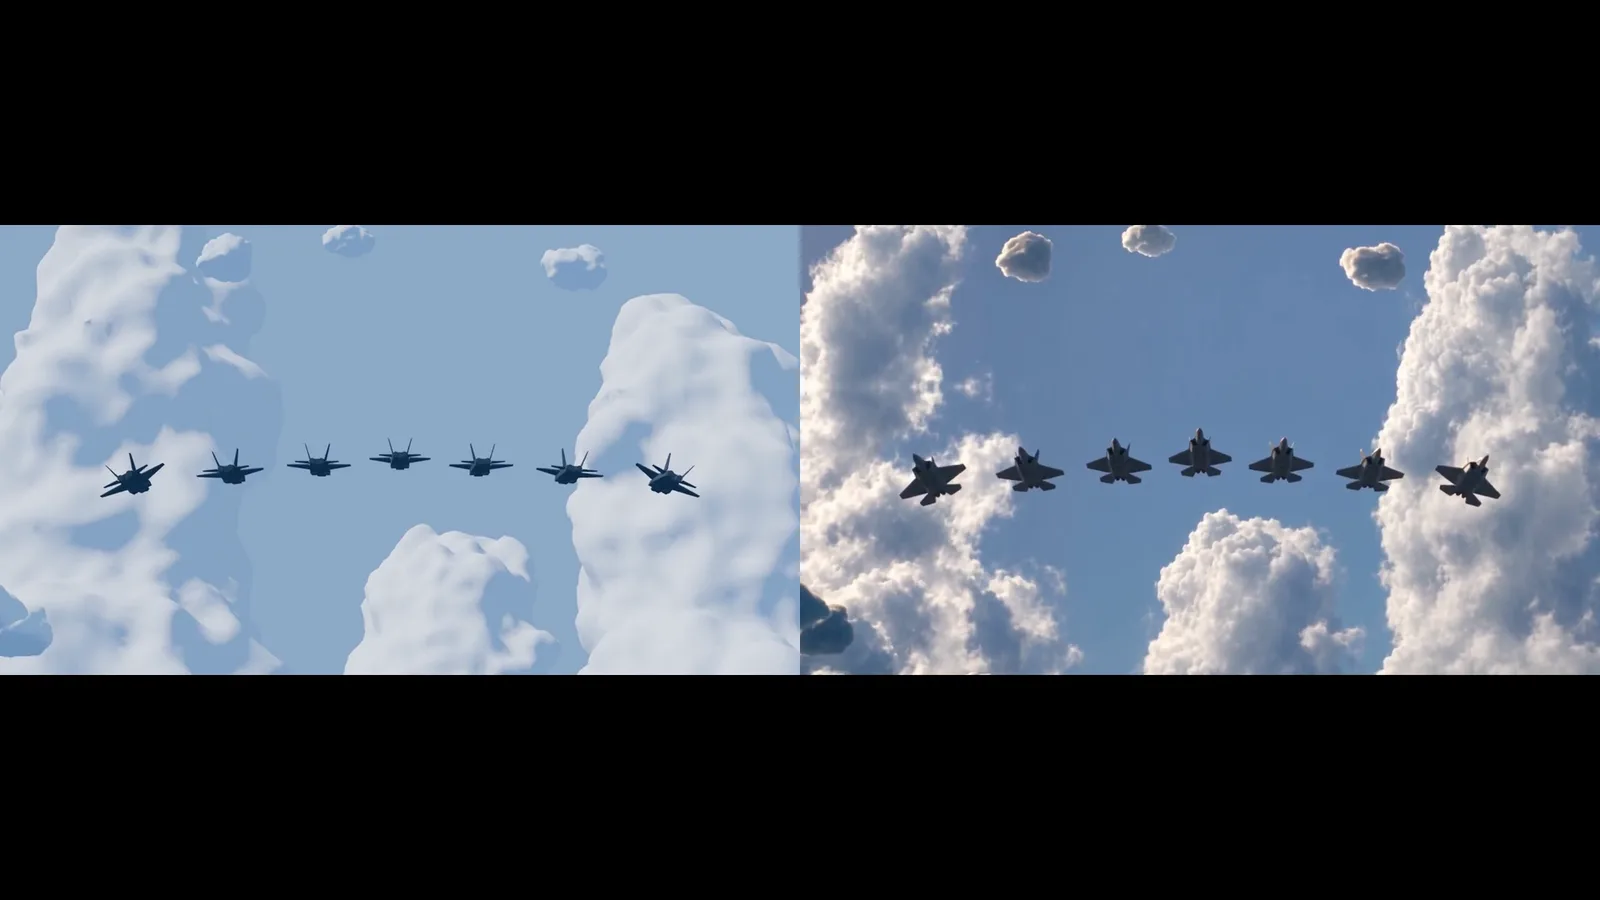
AI video generation is "making one picture" plus "time." A video is really many pictures flipping by quickly, so the AI draws each frame while also making sure each one flows naturally into the next. This guide explains, in order, how AI makes video, three ways to start a video from text or a photo, how to write prompts that cover the subject, the action, and even the camera movement, and the things AI video still often gets wrong.
The basic idea behind image generation (diffusion models that remove noise bit by bit) is in How AI image generation works and how to write good prompts. This guide adds "movement" on top of that.
At a glance
| Item | Short summary |
|---|---|
| What video AI does | Takes text or a photo and makes a short video clip |
| Biggest difference from image AI | Many frames must connect in time order without drifting apart |
| Ways to start | From text alone, from one photo, or by setting a first and last frame |
| What goes into the prompt | Subject, action, style, camera, composition, focus, mood, and sound if needed |
| Still hard | Accurate physics, changes in an object's state, consistency across a long video |
A comparison: drawing a flipbook
If you draw a picture on each corner of a notebook's pages, each one a little different, and flip through them quickly, you get an animation of a bouncing ball. This is called a flipbook.
A good flipbook needs two things.
- Each page has to look right. Image AI is good at this.
- Flipping has to look smooth. If the ball suddenly changes color, or a tree in the background vanishes and reappears, it looks wrong.
Most of the difficulty in AI video generation comes from the second point. In video, each picture is called a frame, and usually dozens of frames go by every second. Even a short clip of a few seconds means drawing dozens to hundreds of pictures that do not drift apart.
How it works: splitting video into small "spacetime pieces"
Here is the basic structure of Sora, the video generation model OpenAI published (a service whose API access ended in September 2026).
- Compress: First the video is compressed into a small summary form (a latent space). Just as image AI packs a picture into a compressed pack, video is also shrunk to a size that is easy to calculate.
- Cut into pieces: The compressed video is split into spacetime patches. Each piece bundles one part of the screen (space) with a short stretch of time (time). They are small blocks cut from the video across, down, and along time.
- Remove noise: Starting from noise pieces, the model refines them many times until they become clean pieces that match the text description. It is the same idea as the diffusion model for images, extended along time.
In this structure, a photo is treated as "a video with only one frame" and handled the same way. This means photos and video can be learned in one framework.
Because each piece holds both space and time, the AI can consider "how this part should change in the next moment" all at once. That is why movement looks more natural than when each frame is drawn separately and then joined. Each company's detailed structure differs, though, and much of it is not public, so think of this as one typical approach.
Three ways to start
You can roughly divide the approaches into three, based on what you give the video AI to start with.
| Method | What you give it | Advantage | Good for |
|---|---|---|---|
| Text → video | A text description only | Simplest | Quickly testing an idea |
| Image → video | One photo or picture to be the first frame | You can set the characters, colors, and composition in advance | When you have a clear scene in mind |
| First and last frames | Two images: a starting frame and an ending frame | You can decide where it starts and where it ends | When you want to connect two scenes smoothly |
Here are real models as examples. Stability AI's Stable Video Diffusion is an image → video model released as a research preview in November 2023, built on the image model Stable Diffusion. Google's Veo has a feature for setting the first and last frames, and a feature for adding up to 3 reference images of a person, character, or product to be reflected in the video.
In practice, the image → video method is especially useful. First make the opening frame several times with image AI and pick the one you like, then animate that picture, and the result is much easier to predict. Video often takes more time and money to make than images, so set the direction first at the cheap, fast stage.
Good prompts: adding "action" and "camera" to an image prompt
If the skeleton of an image prompt was subject, background, and style, a video prompt adds what moves and how and how the camera moves. These are the elements Google's Veo documentation recommends.
| Element | Meaning | Example |
|---|---|---|
| Subject | The object, person, animal, or landscape in the video | A small sailboat |
| Action | What the subject does | Moving slowly across a calm sea |
| Style | A film genre or feel | Warm documentary, science fiction, film noir |
| Camera position and movement | Where and how it is filmed | An aerial view looking down from the sky, eye level |
| Composition | How large it appears on screen | A wide shot, a close-up |
| Focus and lens | What to show sharply | Shallow focus with a blurred background, a wide-angle lens |
| Mood | Colors and time of day | A warm sunset tone, a blue night |
Compare these two examples.
- Weak example:
a boat on the sea - Better example:
a small white sailboat moving slowly across a calm sea at sunset, an aerial shot looking down from the sky and then slowly moving closer, warm orange tones, documentary feel
In the first example, whether the boat moves, whether the camera moves, and what the light is like are all left to chance. The second is like handing a director a storyboard (a filming plan with the scenes drawn in order).
Camera terms worth knowing
Knowing a few film terms makes it easier to get the camera to move the way you want.
| Term | Meaning | Feel |
|---|---|---|
| Dolly shot | The camera glides forward, backward, or sideways as if on rails | Moving in feels immersive; moving out leaves a lingering feeling |
| Pan | The camera stays in place and only turns left or right | Like sweeping your eyes across a wide landscape |
| Aerial view | Looking down from high up, like a drone | Shows scale and place at a glance |
| Top-down | Looking straight down from directly above | Like a map or a cooking video |
| Worm's-eye | Looking up from ground level | Makes the subject look big and grand |
| Orbit | Circling around the subject | A sense of depth, like a product showcase |
If you put several camera movements into one clip, the AI is easily confused. Make one camera movement per clip your default. If you need several movements, it is easier to make separate clips and join them in editing.
Writing sound as text
Some video AI tools now make sound too. In Veo, you write sound like this.
- Dialogue: put the words to be spoken in quotation marks. Example: The captain says, "We'll arrive soon."
- Sound effects: describe the sound clearly. Example: Tires screech loudly and an engine roars.
- Ambient sound: describe the soundscape of the place. Example: The sound of gentle waves and seagulls in the distance.
What AI video still often gets wrong
Below are the limits OpenAI described in its 2024 Sora technical report.
| Limit | What happens | Example |
|---|---|---|
| Physics | Cannot accurately imitate basic physics such as glass shattering | A cup breaking may look strange |
| State changes | In interactions like eating food, changes in an object's state are not always right | Someone takes a bite, but the bread is still whole |
| Long videos | The longer it gets, the more things stop matching or objects suddenly appear | The scene may fall apart toward the end |
The limits of image AI (exact text, keeping the same person across several images) carry over to video as they are, and they stand out even more once time is added. So try these tips.
- Short and many: rather than making a long video in one go, make several short clips, pick the good ones, and join them.
- Set the first frame as a picture first: lock in the characters and colors with the image → video method.
- Avoid complex physics scenes: for scenes with pouring water or breaking objects, try several times, or hide it with the camera angle.
- Use reference images: if the same person or product needs to appear in several clips, add reference images.
AI video often goes through cutting and joining in an editing program. Think of the AI as the camera crew, and the person as the director and editor.
Using it responsibly
AI-generated labels: Videos made with Veo include a SynthID watermark (an invisible label that marks content as AI-generated). When you publish a video, saying in the description that it was made with AI helps avoid misunderstanding by viewers.
Real people and events: Video looks real more easily than photos. As a basic rule, do not make videos that imitate a real person's face or voice, or that present events that never happened as if they were real. Many services restrict this kind of use in their terms, so also check the usage policy of the service you use.
Copyright: Who holds the rights to AI-made video, and whether you may make something resemble an existing film or character, depends on the country and the service terms, and is still under debate. Before commercial use, check the terms, and it is safer to avoid requests that imitate real trademarks or characters. More details are in Copyright basics for AI-made images and text.
Summary
| Item | Summary |
|---|---|
| AI video generation | A technology that makes many pictures in time order without them drifting apart |
| How it works | Compresses video, splits it into spacetime pieces, and builds it by removing noise |
| Ways to start | From text alone, from one photo, or by setting a first and last frame |
| What goes into the prompt | Subject, action, style, camera, composition, focus, mood, sound |
| What to watch out for | Physics and consistency in long videos, AI-generated labels, real people, copyright |
Read next
- How AI image generation works and how to write good prompts
- How to write good prompts: 5 principles from the official guides
- Copyright basics for AI-made images and text
References
- OpenAI, "Video generation models as world simulators" (2024-02-15): https://openai.com/index/video-generation-models-as-world-simulators/
- Google AI for Developers, Gemini API "Generate videos with Veo": https://ai.google.dev/gemini-api/docs/veo
- Stability AI, "Introducing Stable Video Diffusion" (2023-11-21): https://stability.ai/news-updates/stable-video-diffusion-open-ai-video-model
- Google Research Blog, "High Fidelity Image Generation Using Diffusion Models" (2021-07-16): https://research.google/blog/high-fidelity-image-generation-using-diffusion-models/